A preprint’s case for AI that helps shape research questions
The preprint proposes a framework for AI that helps revise the course of research itself, rather than only answering questions or operating tools within a predefined task. It is an authors’ proposal in a newly submitted arXiv preprint, not evidence of peer-reviewed or independently verified capability.
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
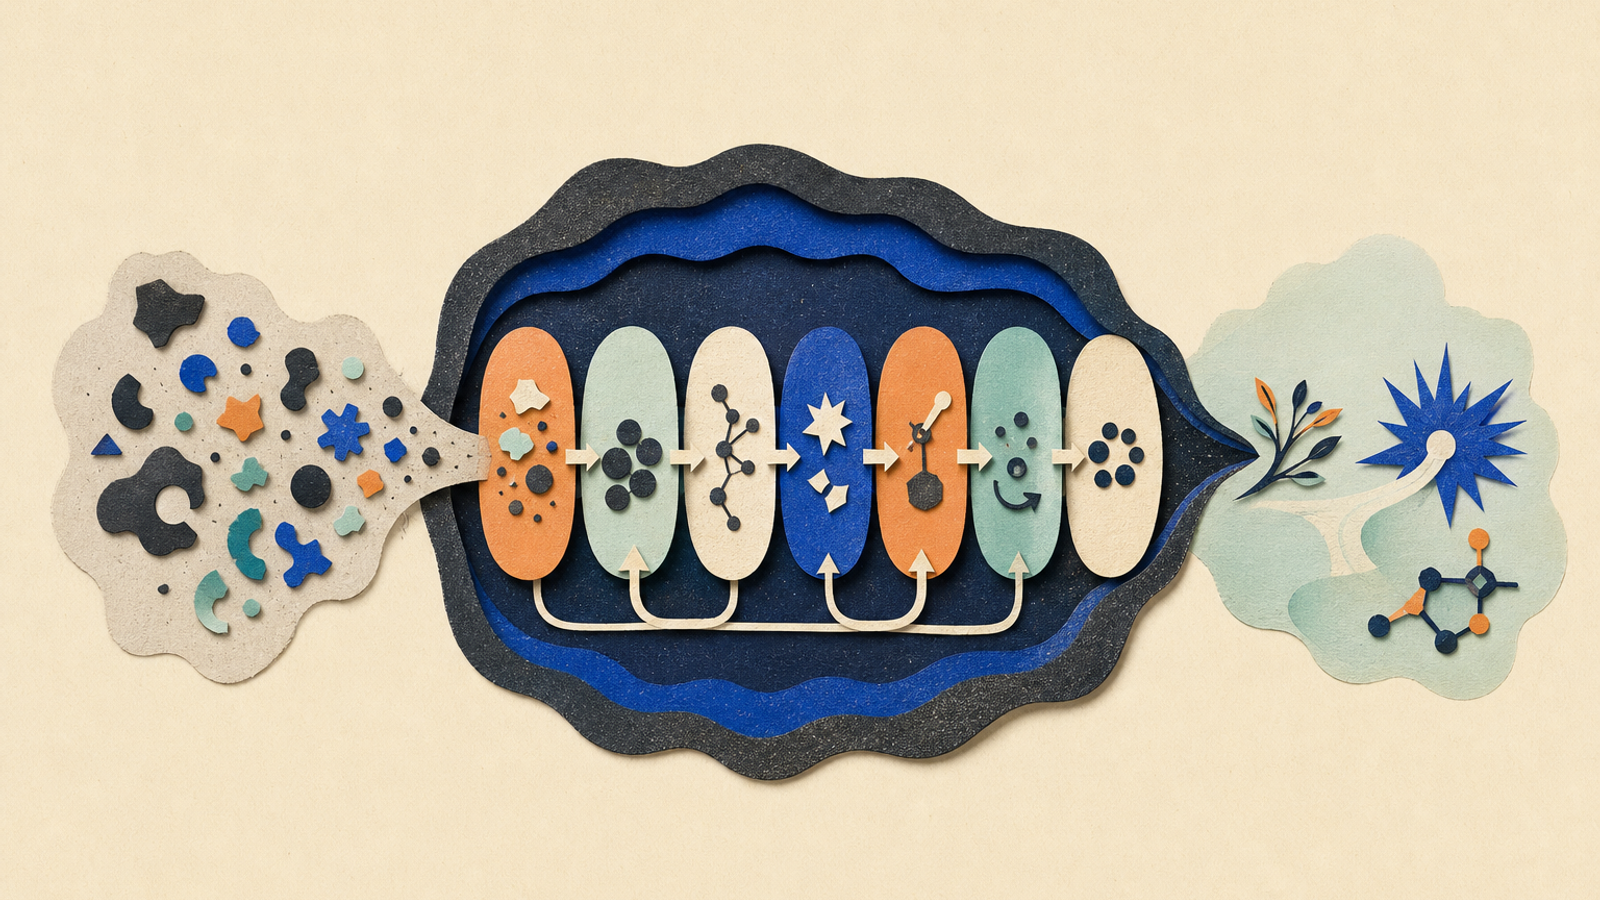
A newly listed arXiv preprint proposes “Discovery Foundation Models” as AI systems intended to participate in open-ended research, including revising the questions, representations and hypotheses involved. The paper is a version-1 preprint by Ling Yang, Zhenfei Yin and Yingcheng Wu, submitted on 14 September 2026. Its abstract presents a framework and named systems, but the supplied evidence does not establish peer review, reproducibility or performance results. [1]
01
What we know now
- 01
arXiv records “Discovery Foundation Models: Toward Open-Ended Discovery Intelligence” by Ling Yang, Zhenfei Yin and Yingcheng Wu as version 1, submitted on 14 September 2026. [1]
- 02
The abstract presents DFMs as general-purpose systems for open-ended discovery with seven coupled capabilities. [1]
- 03
The abstract names Zetema and describes GALILEO in a therapeutic-discovery context, without independently verified outcomes in the supplied evidence. [1]
02
Publication status
arXiv lists this as version 1 of a preprint, submitted on 14 September 2026; the supplied record does not establish peer review.Proposed operating model
The authors describe a revisable research state rather than a system limited to returning a final answer for a fixed prompt.Capabilities named
The abstract lists problem discovery, formulation, representation construction, hypothesis formation, intervention, evidence-grounded revision, and continual improvement.This summarizes the authors’ proposed framework, not independently validated performance. [1]
03
What the term means
The authors use “Discovery Intelligence” for a proposed capability beyond solving problems that people have already defined. In their account, a Discovery Foundation Model, or DFM, is a general-purpose model system for open-ended discovery. [1]
The distinction is therefore about scope and process. A question-answering system may respond to a supplied prompt, while the proposed DFM framework would also help identify problems, frame them and update its approach as evidence changes. This is the authors’ conceptual framing, not an independently established capability threshold. [1]
- Fixed-task systems start with a human-specified question or task; the authors position DFMs as participating earlier, in defining and revising what should be investigated. [1]
- The proposed unit of work is a revisable research state, not solely a final answer. [1]
- Tool use and outcome feedback are described as part of an earlier progression; the paper’s claimed next step is helping construct, test and revise the structures through which knowledge is developed. [1]
04
How the proposed framework works
The abstract groups seven linked capabilities around a research process: discovering and formulating problems; building representations; forming hypotheses; making interventions; revising against evidence; and continually improving discovery activity. [1]
The paper also proposes process-centred evaluation, meaning assessment beyond whether a system produces a final answer. However, the supplied abstract does not provide enough detail to determine the measurements, experiments or comparative findings behind that proposal. [1]
05
What Zetema and GALILEO establish, and what they do not
The authors say they instantiate the framework with Zetema and discuss GALILEO as a therapeutic-discovery system with a closed physical discovery loop. Those descriptions indicate the intended application of the framework. [1]
They do not, on the evidence supplied here, demonstrate that either system performs reliably, outperforms alternatives, can be reproduced, or has produced validated therapeutic outcomes. Readers should keep the framework proposal separate from any claim of demonstrated impact. [1]
- Zetema is described as combining research-state dynamics, verification and experimental gates, external grounding, and cross-task evolution of discovery skills. [1]
- GALILEO is described as linking dry-lab reasoning, robotic and hands-on wet-lab experimentation, external biological evidence, and iterative revision. [1]
06
Why the distinction matters
The proposal shifts attention from AI that completes a given task to AI intended to help manage an evolving inquiry. If developed and evaluated rigorously, that would require evidence not only about answers, but also about problem selection, revisions, verification and experimental decision-making. The latter is an implication of the authors’ framing, not a demonstrated result in the supplied record. [1]
For now, the concrete development is the submission of a preprint. Its primary record is available at https://arxiv.org/abs/2609.15973v1. [1]
07
What readers can do next
Read the primary arXiv record for the authors’ abstract and submission details. Treat the work as a proposal to examine, rather than a validated account of system capability. [1]
08
Limits of this edition
This article is based on the arXiv record and abstract supplied in the packet, not an independent evaluation of the full work. [1]
The evidence does not establish peer review, specific experimental results, benchmarks, comparative performance, reproducibility, or the availability and contents of linked code and website materials. [1]
The therapeutic-discovery example is an authors’ description. The supplied source does not independently verify therapeutic outcomes. [1]
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
15 Sept 2026
Nuha-Speech: what an Arabic speech-LLM preprint reports, and what is not yet known
Nuha-Speech is an arXiv preprint describing an Arabic speech-LLM research initiative. Its authors report a speech question-answering corpus with more than 1.5 million training samples, supervised fine-tuning of Qwen-Omni variants, and an evaluation framework. The available primary record does not establish peer review, public release of materials, performance results, or independent replication.
14 Sept 2026
Preprint Proposes an Adaptive Drive for Continuing AI Agents
An unreviewed arXiv preprint proposes an adaptive internal drive, termed an artificial id, for AI agents that continue and retain state across tasks. The author reports a minimal virtual experiment and argues that future systems need a persistent alignment boundary, but the supplied evidence does not independently validate the mechanism, its results, or its scalability.
12 Sept 2026
Preprint reports faster repeated-data degradation in Mixture-of-Experts models
An unreviewed arXiv preprint reports that MoE language models in the authors' experiments were more vulnerable than dense models to repeated training data. The authors report that regularization mitigated the effect, but did not match all-unique-data training. The result requires fuller methodological review and independent replication.