Imagine3D-LLM proposes a compact 3D scene step before answers
An arXiv preprint describes training a multimodal language model to form a compact 3D Gaussian Splatting representation from multi-view images before answering. Its authors report improved benchmark performance, but the supplied abstract contains no scores or benchmark names and does not independently verify the claims.
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
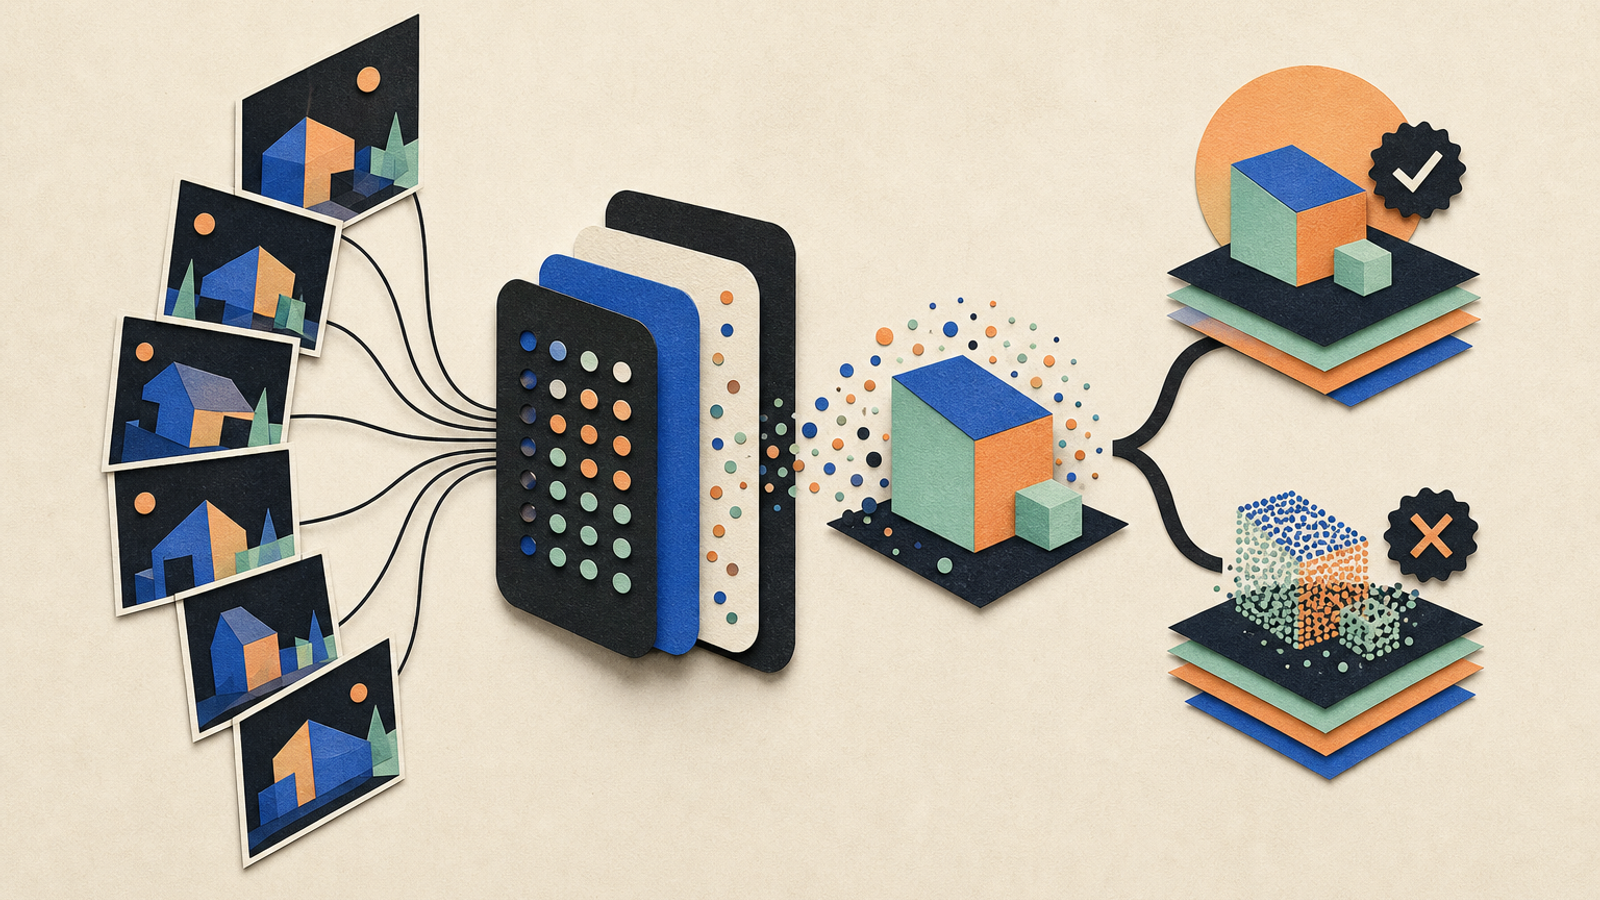
Imagine3D-LLM is an arXiv preprint proposing that a multimodal language model should form a compact 3D scene representation from several images before producing an answer. Its authors report stronger results than prior approaches on multiple spatial-reasoning and 3D-understanding benchmarks, but the supplied abstract gives no benchmark names or numbers, and the claims have not been independently verified here. [1]
01
What we know now
- 01
[1] arXiv, “Imagine3D-LLM: Teaching MLLMs to Imagine 3D Scenes Before Answering,” version 1, submitted 29 September 2026: https://arxiv.org/abs/2609.38177v1.
- 02
The supplied primary evidence is an arXiv abstract record; it is not evidence of peer review or independent replication.
02
Record status
The work is listed on arXiv as version 1, submitted on 29 September 2026.Input setting
The proposal addresses reasoning from multiple views of a scene.Internal representation
The authors describe decoding learned summary tokens into a compact 3D Gaussian Splatting representation.Reported evaluation
The authors say the method surpassed earlier approaches on several benchmarks, without names or figures in the supplied abstract.High-level method and evidence status from the arXiv record.
03
What the preprint proposes
The authors describe Imagine3D-LLM as a multimodal large language model intended for multi-view scene reasoning. Rather than relying only on fine-grained cross-view pixel correspondences or features from 3D geometry models, the proposed approach aims to build a coarse scene-level representation before answering. [1]
According to the abstract, training combines the usual next-token prediction objective with photometric reconstruction supervision for the summary-token-derived 3D representation. This is a method description from the authors, not an independent evaluation. [1]
- The authors frame the problem as integrating evidence from several views into a coherent understanding of a 3D scene.
- Their model adds a small set of trainable summary tokens after image tokens.
- Those tokens are decoded into a compact 3D Gaussian Splatting representation, and the model conditions its answer on that representation.
04
What results are reported
The authors report that reconstruction supervision strengthens correspondence between image features from different frames, even though the direct reconstruction objective applies only to the summary tokens. They also report better performance than previous approaches across several relevant benchmarks. [1]
These are author-reported findings. Without scores, benchmark definitions, baselines, or an independent replication in the supplied material, the size and practical significance of any improvement cannot be determined. [1]
- The authors say reconstruction supervision improves cross-frame correspondence in the model's image features.
- They report outperforming prior methods on multiple spatial-reasoning and 3D-understanding benchmarks.
- The supplied abstract provides neither named benchmarks nor numerical comparisons.
05
Status and why it may matter
For readers tracking multimodal AI research, the preprint is a concise example of a scene-representation approach to multi-view reasoning: the model is trained to generate a compact 3D form as part of answering. The record establishes that this proposal was posted to arXiv, but it does not establish that the approach is ready for use or that its claimed gains generalize beyond the undisclosed evaluations. [1]
arXiv lists the work as version 1, submitted on 29 September 2026. It also carries a NeurIPS 2026 comment, whose meaning is not clarified by the supplied evidence. [1]
- arXiv lists version 1 as submitted on 29 September 2026.
- The record is categorized in computer vision and pattern recognition and computation and language.
- The primary record is https://arxiv.org/abs/2609.38177v1.
06
What readers can verify
The supplied record supports a high-level reading of the proposal, not a performance decision or deployment assessment.
- 01
Read the primary arXiv record and treat the work as a preprint: https://arxiv.org/abs/2609.38177v1.
- 02
Do not infer benchmark scores, supported data, compute needs, code availability, or peer-review status from the supplied abstract.
- 03
Treat the NeurIPS 2026 note as an unexplained record comment, not confirmed acceptance.
07
Limits of this edition
This article is limited to the supplied arXiv record and abstract rather than a full-paper assessment. [1]
Benchmark names, baseline methods, quantitative results, training data, compute requirements, and stated limitations are not available in the supplied evidence. [1]
The record does not establish peer review, independent replication, code availability, model weights, a demonstration, or a usable project-page address. [1]
Its comments field says “NeurIPS 2026,” but the supplied record does not establish whether that means submission, acceptance, or another status. [1]
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
20 Sept 2026
Paint-Anything claims more precise hex-colour control for image AI
The Paint-Anything preprint proposes a shared hex-prompt approach for setting object colours in AI image generation and editing. Its authors describe Paint-500K and ACBench and report gains over a FLUX.2-4B base model, but the supplied evidence does not establish peer review, replication, public implementation releases, or full evaluation details.
28 Aug 2026
Preprint proposes visual-dependence controls for continual multimodal model updates
The authors propose a Visual Dependence-Aware framework for continual, unlabeled post-training of multimodal language models. Its two mechanisms are intended to reduce cross-modal forgetting and support new-task adaptation, but the supplied arXiv record does not provide enough experimental detail to verify performance, costs, or reproducibility. [1]
4 Sept 2026
ShallowStream proposes shallow indexing for streaming video queries
ShallowStream is an arXiv preprint proposing shallow-layer indexing for incoming video frames and deeper processing when answering queries. Its authors report up to 52.1x lower per-frame prefill latency and up to 11.9x lower 10-second end-to-end latency, but the supplied record does not permit independent assessment of those claims or establish peer review. [1]