A preprint proposes reading diffusion transformers’ changing contextual tokens
An arXiv preprint describes a reader that maps internal contextual tokens from multimodal diffusion transformers to a frozen language model so it can answer questions about an emerging image. The authors report that global semantics can be read early and finer details later, and introduce Contextual Alignment as a training technique. Those results remain author-reported and unquantified in the supplied record; methods, benchmarks, results, limitations, peer review, and replication are not established.
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
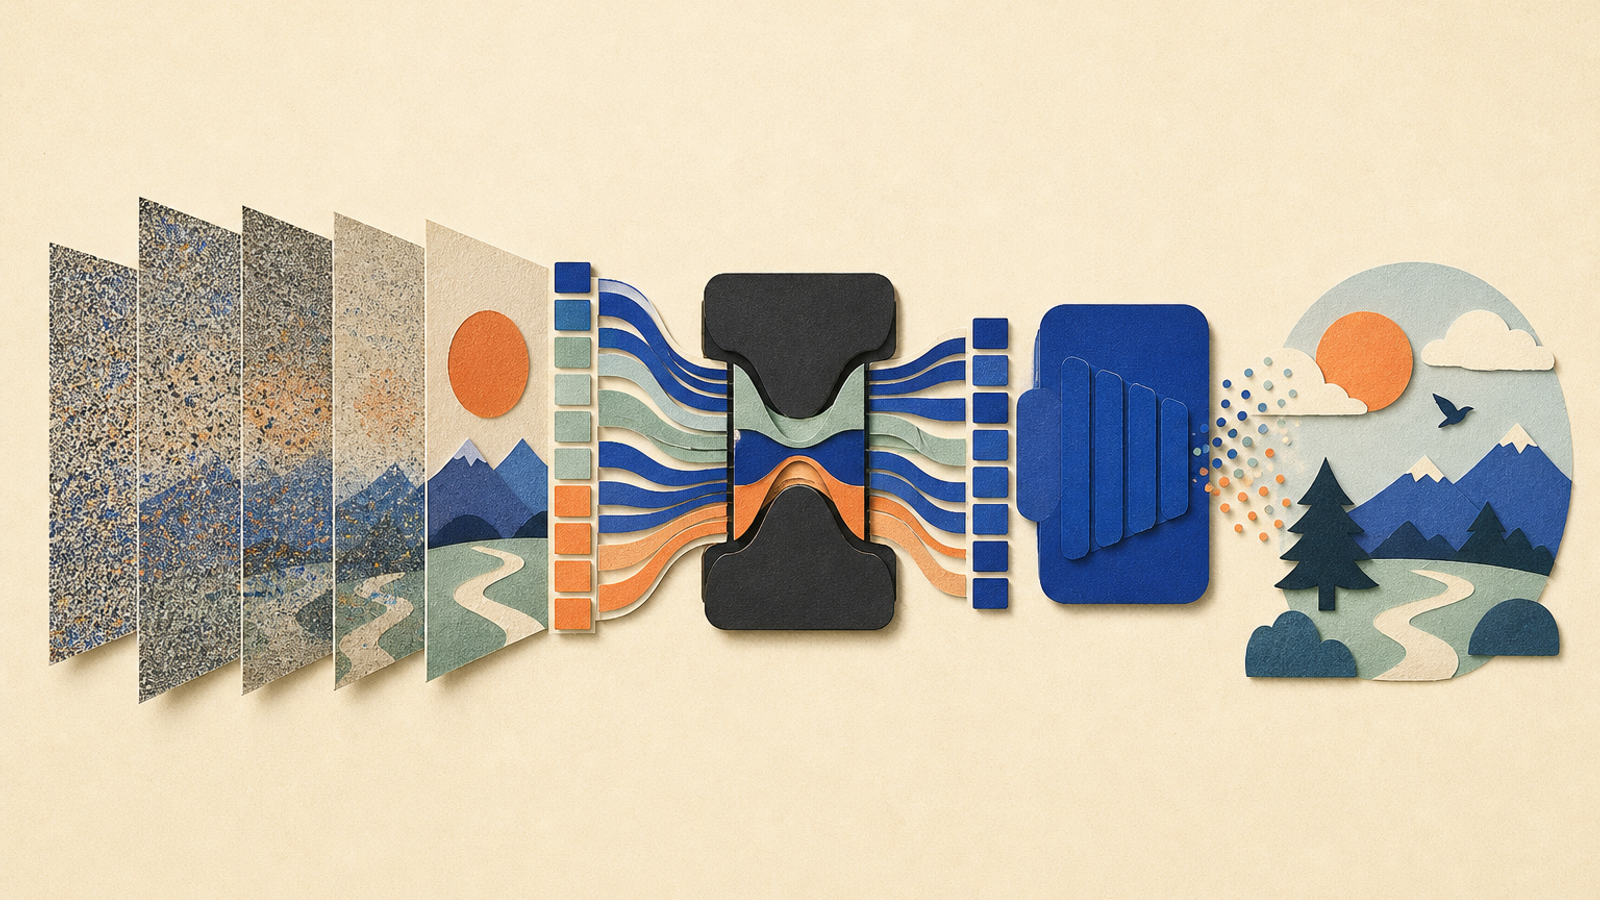
A new arXiv preprint proposes a way to interrogate changing text-side representations inside multimodal diffusion transformers while they generate an image. Its authors say these contextual tokens can reveal information about the emerging scene, but the supplied record does not include the detailed experiments needed to assess accuracy, robustness, or practical usefulness. [1]
01
What we know now
- 01
[1] arXiv, “Learning to Read the Contextual Tokens in Diffusion Transformers,” version 1, submitted 5 October 2026: https://arxiv.org/abs/2610.06844v1.
- 02
The supplied complete primary record contains the paper abstract and bibliographic metadata, but not detailed experimental evidence.
02
Publication status
The work is listed as arXiv version 1, submitted on 5 October 2026. The supplied record does not establish peer review.Proposed reader
Authors describe a lightweight bottleneck network connecting intermediate contextual tokens to a frozen language model’s input space.Reported decoding pattern
The authors say broad, generation-specific semantics become readable early, while finer detail becomes readable later in denoising.Evaluation detail supplied
The available evidence does not provide datasets, baselines, sample sizes, error rates, or quantitative outcomes.A compact view of the paper’s stated method, reported pattern, and evidentiary boundary.
03
What was published
The source is an arXiv preprint in computer vision, also classified under artificial intelligence, graphics, and machine learning. An arXiv listing records a public research submission; it does not by itself demonstrate peer review or independent validation. [1]
- The paper is titled “Learning to Read the Contextual Tokens in Diffusion Transformers.”
- The arXiv record names Omer Dahary, Etai Sella, Hadar Averbuch-Elor, Daniel Cohen-Or, and Or Patashnik as authors.
- It was submitted to arXiv on 5 October 2026 as version 1.
04
The method the authors propose
The authors describe a lightweight bottleneck network intended to make an internal representation legible through natural-language questions. In their account, the system does not require changing the large language model: the learned bottleneck maps the diffusion model’s intermediate contextual tokens into that model’s input space. [1]
This is a research-method claim from the paper’s abstract. The supplied evidence does not describe architecture choices, training data, training procedure, comparison systems, or conditions under which the reader fails. [1]
- Multimodal diffusion transformers process visual and textual representations jointly during generation.
- The authors call the repeatedly updated text tokens “contextual tokens.”
- Their proposed reader maps intermediate contextual tokens into the input space of a frozen large language model, which is then used to answer questions about an image still being generated.
05
What the preprint says can be learned
The central reported finding is temporal: according to the authors, broad semantics of the particular generated image appear in the contextual tokens early in the denoising process, while more detailed information becomes readable as generation proceeds. [1]
The abstract characterises this as evidence that contextual tokens hold a rich global representation of the developing scene. That interpretation and the reported decoding ability remain unverified from the supplied record because it provides no benchmark definitions, accuracy measurements, examples, or failure analysis. [1]
- The authors say global scene information can be decoded from contextual tokens.
- They report that attributes not fully specified by the prompt may be readable early in denoising.
- They say finer-grained details become readable later.
- They also report that information remains decodable with an empty prompt, which they interpret as image-specific information accumulating from the evolving visual representation.
06
Contextual Alignment remains a reported result
Beyond interpretation, the authors present Contextual Alignment as a way to train a model toward more visually meaningful contextual tokens. They claim this improves generation quality and distributional coverage. [1]
The abstract does not supply the size of any change, the evaluation protocol, the reference baselines, or the underlying human-preference measurements. Readers therefore cannot determine from this record whether the reported association or training effect is large, generalisable, or reproducible. [1]
- The authors introduce a training technique called Contextual Alignment.
- They say it reinforces visual-semantic information in contextual tokens.
- They report improved generation quality and distributional coverage.
- They also say generations with more readable contextual representations tend to receive higher human-preference scores.
07
Why the distinction matters
For readers following generative-image research, the paper is notable because it frames changing text-side tokens as a potential source of information about an image before generation completes. If confirmed through detailed experiments and replication, this could be relevant to research on model interpretability and training objectives. [1]
For now, the warranted conclusion is narrower: the authors have posted a preprint describing a reader and reporting promising observations. Its performance, limits, and applicability outside the authors’ evaluation remain unknown from the available evidence. The primary source is the arXiv record: https://arxiv.org/abs/2610.06844v1 [1]
- The work offers a possible research direction for examining internal states during diffusion generation.
- It does not yet establish a dependable diagnostic product, a general-purpose interpretability technique, or an improvement that can be assumed across models.
- The primary record links to the paper, but the supplied evidence does not confirm accessible implementation or data resources.
08
What readers can do next
Treat the paper as an early research claim rather than a validated tool or production capability.
- 01
Read the primary arXiv record and, if needed, its linked full paper for methods and experiments.
- 02
Check whether later versions, peer review, code, data, or independent reproductions become available.
- 03
Compare any reported results with the paper’s datasets, baselines, metrics, and failure cases before relying on the technique.
09
Limits of this edition
This is a single preprint record, not evidence of peer review or independent replication. [1]
The supplied material does not include full methods, datasets, baselines, metrics, sample sizes, error rates, or reported failure cases. [1]
No acquired code, model, data, or confirmed project-page access path is provided in the evidence. [1]
Claims about image quality, distributional coverage, and human-preference relationships are author-reported in the abstract and are not quantified in the supplied material. [1]
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
5 Sept 2026
Preprint questions whether readable reasoning traces reveal step importance
An arXiv preprint reports that the text of a chain-of-thought step only partly reveals its functional importance under the authors' reward-based measure. The authors say capable LLM judges beat a prevalence baseline but remained below a noise ceiling. They also report strong improvement from a fine-tuned step-level critic on incorrect responses, while performance on correct responses remained distant from the ceiling. The supplied evidence is limited to a preprint record and abstract. [1]
4 Oct 2026
GALA preprint proposes linear blendshapes for cheaper Gaussian avatar animation
An arXiv preprint introduces GALA, which its authors say distils pretrained 3D Gaussian avatar animation into a shallow coefficient predictor and a linear blendshape basis. They report lower CPU animation cost and mobile frame rates up to 60 fps, but the supplied evidence does not establish peer review or independent validation and lacks detailed benchmarks.
12 Sept 2026
Small vision-language models show a field-image gap in species ID, preprint reports
The authors’ unreviewed benchmark reports that all tested models identified species far above chance, but that every model performed worse on camera-trap imagery than on clean photographs. The specialist BioCLIP reportedly outperformed the tested general-purpose vision-language models, while some open-set outputs named taxonomically nonexistent species. These findings support testing field images and validating names, not treating the benchmark as proof of deployment readiness. [1]