ScienceBuddy preprint outlines a two-loop approach to improving scientific agents
ScienceBuddy is described by its authors in a newly recorded arXiv preprint as an interactive scientific-research workspace whose continual-learning design combines harness improvement with model training. The supplied source confirms the preprint record and the authors' stated framework, but not performance, availability, peer review, or independent replication.
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
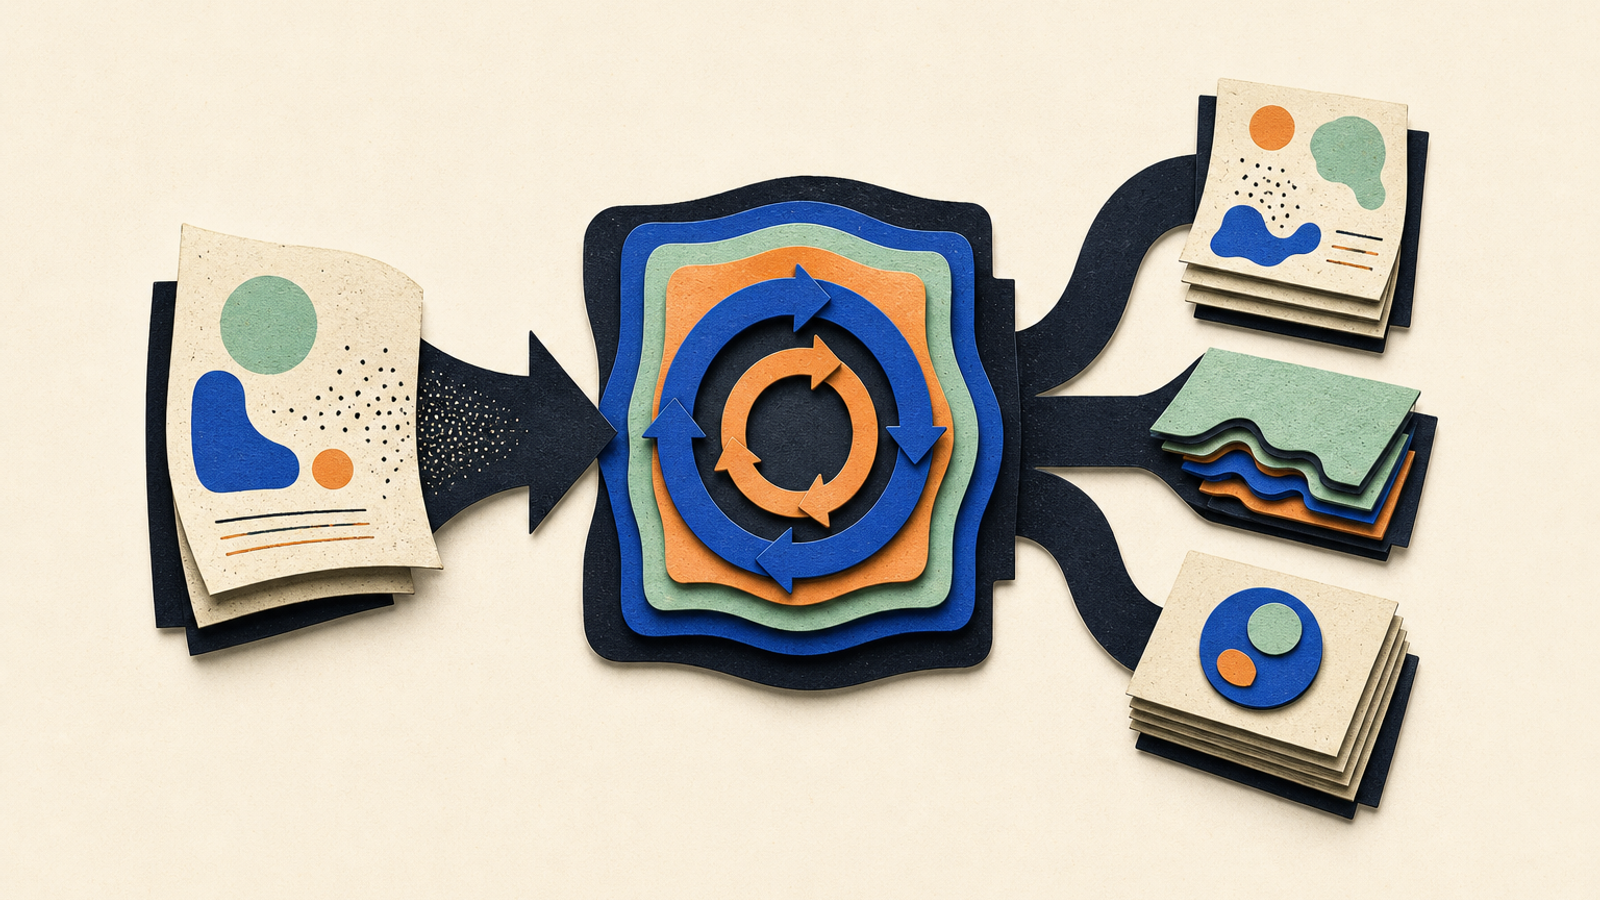
A new arXiv preprint describes ScienceBuddy, which its authors present as an interactive workspace for scientific research tasks and continual improvement of scientific agents. The record confirms that the first version was submitted on 15 September 2026; it does not establish peer review, independent validation, or verified public access to the associated software.
01
What we know now
- 01
[1] arXiv primary record for ScienceBuddy, version 1, submitted 15 September 2026: https://arxiv.org/abs/2609.17523v1.
- 02
The supplied record contains the title, authors, abstract, submission timestamp, and references to website and code links, but not verified destinations for those links.
02
Record status
arXiv lists version 1 as submitted on 15 September 2026. A submission record is not peer review.Proposed learning structure
Authors describe an inner loop for harness improvement with a fixed model and an outer loop that trains the model under that improved harness.Benchmark scope stated
The abstract says benchmark cases span four scientific task families, but it does not name them in the supplied record.Evidence status
The supplied record contains authors' abstract claims, not an independent assessment of performance, availability, or impact.A compact view of what the arXiv abstract records and the limits of that record.
03
What the preprint records
The primary source is an arXiv preprint record, rather than a peer-reviewed publication or an independent product review. It establishes that the manuscript was posted and describes the authors' proposal, but it does not by itself verify how the system performs in practice or whether it is generally accessible.
Primary source: https://arxiv.org/abs/2609.17523v1
- arXiv records “ScienceBuddy: Recursive-in-Recursive Self-Improvement for Interactive Scientific Agents” as version 1, submitted on 15 September 2026.
- The listed authors describe it as an interactive scientific research workspace intended to help researchers carry out scientific tasks.
- They say requests, feedback, and execution evidence can be turned into tasks and evaluation rubrics for continual learning.
04
The proposed mechanism
In the authors' account, the harness shapes the training experience, while model learning may create further opportunities to adapt that harness. This is a proposed framework described in the abstract, not an independently established result.
The abstract says the paper includes case studies covering researcher interaction, harness refinement, and model learning.
- The inner recursion is described as improving the harness while keeping the model fixed.
- The outer recursion is described as training the model under the improved harness.
- The authors call the combined approach “recursive-in-recursive self-improvement.”
05
What cannot be concluded yet
It would be premature to infer that the approach improves scientific work, outperforms other systems, or is ready for routine use. Those conclusions would require the missing methodological and results context, along with review or independent replication.
Although the arXiv page lists website and code links, this evidence packet does not verify where those links lead or whether readers can access and run the project.
- The abstract says benchmark cases span four scientific task families.
- It does not name those families in the supplied record.
- It also does not provide quantitative outcomes, comparisons with alternatives, or enough evaluation detail to judge effectiveness.
06
Why the distinction matters
For readers following scientific-agent research, the notable item is the authors' attempt to couple workflow-level harness changes with model training. The responsible takeaway is narrower: an initial preprint records the proposal and its claimed scope, while key evidence needed to assess it is not present in the abstract record.
- Use the preprint as a description of a research proposal and reported release, not as proof of validated capability.
- Check the full paper for task definitions, assessment design, baselines, and any stated constraints.
- Separate claims made by the interested authors from independently confirmed findings.
07
What to check next
The abstract supports a narrow reading of the work. Readers considering the project should review the paper itself before drawing conclusions about results or access.
- 01
Read the primary arXiv record and, if needed, the linked paper to identify the four task families, methods, baselines, and reported measurements.
- 02
Treat the website and code links as unverified from this evidence packet: their destinations and current accessibility were not assessed.
- 03
Look for peer review, independent replication, and fuller evaluation details before relying on claims about effectiveness or general availability.
08
Limits of this edition
This brief is based on the supplied arXiv record and its abstract, not a full independent technical evaluation.
The abstract does not identify the four task families or provide detailed methodology, measurements, baselines, or evaluation conditions.
Website and code links are listed in the record, but their destinations and accessibility were not verified in the supplied evidence.
No peer-review outcome, independent replication, or independent evaluation is included in the evidence.
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
28 Aug 2026
Preprint proposes visual-dependence controls for continual multimodal model updates
The authors propose a Visual Dependence-Aware framework for continual, unlabeled post-training of multimodal language models. Its two mechanisms are intended to reduce cross-modal forgetting and support new-task adaptation, but the supplied arXiv record does not provide enough experimental detail to verify performance, costs, or reproducibility. [1]
10 Sept 2026
NASA records open release of a lunar-science AI model, with key details still unconfirmed
NASA records an open lunar-science AI release with code, datasets and benchmarks. Its stated results favour the model on polar-ice stability estimation and show comparable outcomes on two other tasks, but the announcement lacks numerical evaluations and identifies lighting variation as a limit for detecting smaller craters.
10 Sept 2026
IdeaAMBIG reports a gap between finding missing method details and clarifying them
The authors of the IdeaAMBIG preprint report a large difference between language models’ ability to find underspecified implementation details and their ability to suggest a clarification after a defect is annotated. In their benchmark, the best reported real-world defect-recovery score was 9.6%, while the reported clarification-action score with a provided defect was 80.6%. These are unreviewed, author-reported results from a single arXiv preprint.