Agensh preprint reports decentralized coordination for up to 1,024 AI agents
The Agensh preprint describes asynchronous, self-organized AI-agent coordination through shared work records, messaging and context. Its authors report improved results as agent counts grew in specified programming benchmarks, including a pandoc result at 1,024 agents. These claims remain preliminary because the supplied evidence establishes neither peer review, independent replication, reproducibility materials nor operating costs. [1]
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
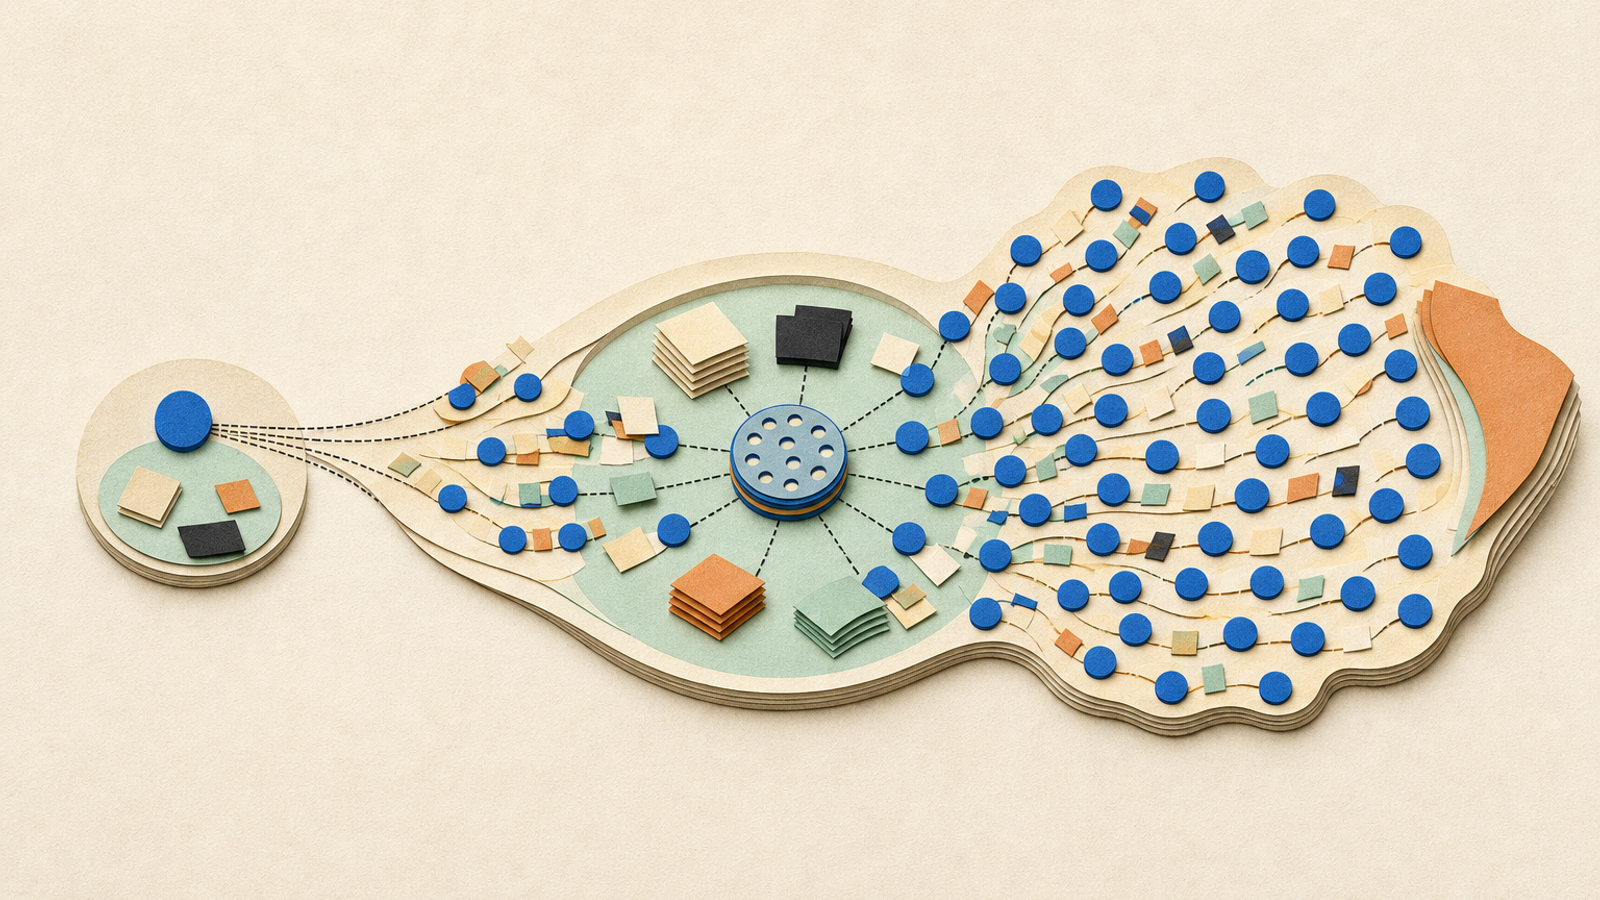
A September 2026 arXiv preprint introduces Agensh, a proposed framework for coordinating many AI agents without a central task allocator. Its authors report higher test-pass rates as agent counts rose in a limited set of programming evaluations, but the supplied record does not establish peer review, replication, cost or reproducibility materials. [1]
01
What we know now
- 01
[1] arXiv, “Agensh: Scaling Organizational Intelligence to 1,024 Agents,” version 1, submitted 22 September 2026: https://arxiv.org/abs/2609.26781v1.
- 02
The supplied complete primary record supports the paper metadata, authors’ design description and reported benchmark figures, but does not establish peer review, independent replication or reproducibility resources.
02
Architecture described by the authors
Workers use a shared workspace, messaging interface and shared context rather than a central orchestrator.ProgramBench result reported at 128 agents
Mean final test-pass rate rose from 19.31% at one agent to 28.78% at 128 agents on five difficult tasks using GPT-5.6-sol (high).Pandoc result reported at 1,024 agents
The authors report a final test-pass rate increase from 33.89% with one agent to 55.06% with 1,024 agents.All performance figures are author-reported results in a single preprint, not independently verified findings. [1]
03
A decentralized coordination proposal
Agensh is presented by its authors as a self-organized multi-agent harness. Instead of assigning work through a single controller, agents coordinate through common work records, messages and retained context. This describes the proposed mechanism; the supplied evidence does not independently verify its operation or advantages. [1]
- The authors describe concurrent workers that repeatedly gather context, claim and self-assign subtasks, act and share findings, verify results, and merge progress asynchronously.
- Their proposed infrastructure has three components: a shared workspace for proposed, ongoing and completed work; a message interface; and shared context for reusable findings and work intentions.
- The paper presents this as a way to avoid a central orchestrator becoming a coordination bottleneck.
04
What the evaluation reports
These are author-reported outcomes from the preprint’s stated setup, rather than independently established performance results. The evidence supplied here does not show whether the pattern holds with other models, task sets, agent reliability conditions or deployment environments. [1]
- On five difficult ProgramBench tasks with GPT-5.6-sol (high), the authors report that scaling from one to 128 agents raised the mean final test-pass rate from 19.31% to 28.78%. They characterize this as about a 49% relative improvement.
- For pandoc, the authors report a rise from 33.89% with one agent to 55.06% with 1,024 agents.
- The abstract also says larger organizations reached comparable test-pass rates earlier, but it supplies no latency measurements in the record provided.
05
Limits on the conclusion
The paper supports a narrow conclusion: its authors report that their coordination design scaled to the stated agent counts and achieved the stated benchmark figures in their evaluation. It does not yet support a general conclusion that decentralized agent organizations are more effective, less costly or practical for broad real-world use. Readers considering the approach should seek the underlying materials and independent tests. [1]
- No public code, prompts, configurations, datasets or other reproduction materials are established by the supplied evidence.
- No token, compute, monetary-cost or infrastructure figures are established for runs with up to 1,024 agents.
- Peer review and independent replication are not established.
06
Source record
The primary record is the arXiv entry for “Agensh: Scaling Organizational Intelligence to 1,024 Agents.” It is the source for both the system description and the reported evaluation figures summarized above. [1]
- Primary source: https://arxiv.org/abs/2609.26781v1
- The record lists Zhihao Zhan, Ting Song, Li Dong, Shaohan Huang, Jianxun Lian, Yan Xia and Furu Wei as authors.
- arXiv records the item as version 1, submitted on 22 September 2026.
07
What to check before relying on the result
Treat the reported figures as preliminary benchmark results, not as validated guidance for deployment.
- 01
Read the primary preprint and distinguish the described design from its reported measurements.
- 02
Ask for reproducibility materials, including code, prompts, configurations and datasets, before attempting to compare results.
- 03
Assess model choice, task mix, token use, compute cost, latency, failure handling and infrastructure needs for a specific use case; the supplied record does not establish these factors.
- 04
Look for peer review or independent replication, neither of which is established by the supplied evidence. [1]
08
Limits of this edition
This is arXiv version 1 of a preprint, submitted on 22 September 2026; the supplied evidence does not establish peer review or acceptance by a publication venue. [1]
The reported benchmark results are the authors’ claims. The supplied record provides no independent validation, full experimental materials, cost data or sensitivity analysis. [1]
The record does not establish token consumption, compute requirements, monetary cost, latency measurements, infrastructure requirements, failure rates, or variation across models and experimental settings. [1]
The figures cover the stated ProgramBench evaluation and pandoc task; they do not by themselves establish performance on other tasks or environments. [1]
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
16 Sept 2026
Preprint proposes a “social harness” for multi-agent AI interactions
The authors of a September 2026 arXiv preprint argue that multi-agent AI systems need a “social harness” for interactions among agents, alongside each agent's personal harness. They report experiments suggesting current tools can fail across trust boundaries and propose layers for prevention, runtime message checks, and later investigation. The available evidence is limited to the preprint record and abstract. [1]
23 Sept 2026
Harness-Zero preprint proposes distilling agent-harness behavior into model weights
Harness-Zero is an arXiv preprint proposing agent-as-harness distillation: an optimized harness guides an intermediary that creates corrections in a fixed target harness's action space for fine-tuning. The authors report that the resulting model retained useful behavior after a specialized harness was removed, including a macro-average task-success change from 23.3% to 44.3%. The supplied evidence does not independently verify those results. [1]
21 Sept 2026
Preprint examines coding agents’ claims of completed file reviews
An arXiv preprint introduces a five-scenario benchmark for comparing coding agents’ final review summaries with file coverage. Its authors report frequent incomplete reading and inadequate disclosure in incomplete runs, but peer review, replication, and broader generalisability are not established by the supplied record. [1]