MemPilot proposes runtime choices for multimodal agent memory
MemPilot is a preprint proposing a policy that dynamically chooses between retrieving prepared memory and curating raw multimodal history. Its authors report improved performance-cost-latency trade-offs on five benchmarks, but the supplied evidence does not provide the details needed to independently evaluate that result.
This edition passed Imananq's enhanced publication checks. Some material claims remain explicitly attributed to official or company sources because no independent source is currently bound to this edition. The engine continues checking approved sources and will add corroboration only through a new edition that passes the full gate.
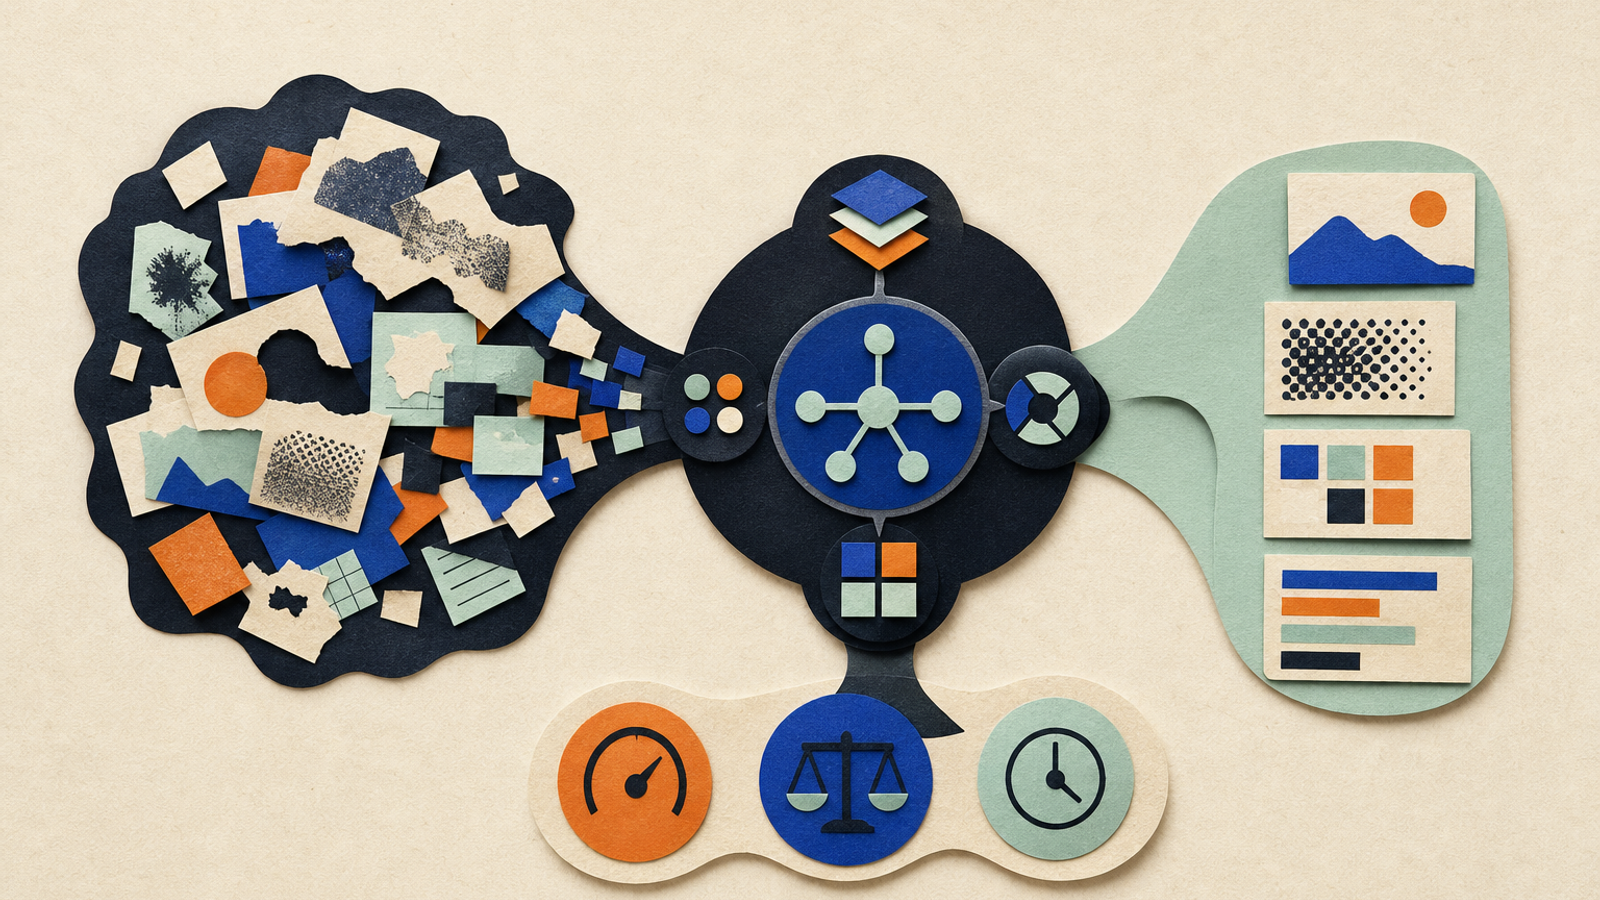
MemPilot is an arXiv preprint that proposes a runtime controller for deciding how a multimodal LLM agent should use prior interaction history. Its authors say the system can choose between retrieving already prepared memory and asking language or vision-language models to curate relevant raw history for the current query. The claims are currently supported only by the authors’ preprint record. [1]
01
What we know now
- 01
[1] arXiv record and abstract for “MemPilot: Orchestrating On-Demand Multimodal Memory Curation for LLM Agents,” version 1: https://arxiv.org/abs/2610.06830v1.
- 02
The complete supplied primary evidence is the arXiv record; no independent corroborating source was supplied.
02
Publication status
The record is an arXiv version 1 preprint, not evidence of peer review or independent replication.Submission date
arXiv records version 1 as submitted on 5 October 2026.Reported evaluation scope
The authors say they tested five multimodal agent-memory benchmarks, but the supplied abstract does not name them.Code record
arXiv says code is available, but the acquired evidence does not identify or inspect its destination.Status and scope based solely on the arXiv record.
03
What the preprint proposes
The authors present MemPilot as a framework for on-demand multimodal memory curation in LLM agents. Rather than committing to a single fixed memory-processing path, they describe a multi-step policy trained with reinforcement learning to choose a processing route as an interaction unfolds. [1]
The paper also says it adapts objective-wise advantage decoupling and introduces prefix-based marginal utility estimation for training and credit assignment. These are method descriptions from the authors, not independently assessed capabilities. [1]
- It selects between retrieval from query-agnostic memory and query-specific curation of raw multimodal history.
- The authors say the policy can control how much evidence to use, the curation instruction, model selection, and whether visual material is accessible.
- The stated objective is to allocate runtime computation under different performance, cost, and latency preferences.
04
What evidence supports the performance claim
The authors report favourable trade-offs across optimisation preferences and a broader performance-cost-latency frontier than existing trade-off-aware baselines. However, the supplied record does not include the benchmark names, numbers, experimental setup, or methodology needed to verify the comparisons independently. [1]
As a result, the record establishes that the authors made these claims in a publicly listed preprint, but it does not establish that the claimed performance advantage will hold in other agent systems or deployments. [1]
- The authors report experiments across five multimodal agent-memory benchmarks.
- They say preference sweeps gave broader performance-cost-latency frontiers than trade-off-aware baselines.
- The available abstract supplies no benchmark identities or quantitative comparisons.
05
Record and availability
MemPilot, titled “MemPilot: Orchestrating On-Demand Multimodal Memory Curation for LLM Agents,” is listed on arXiv as version 1. The primary record is available at https://arxiv.org/abs/2610.06830v1. [1]
No peer-review outcome, publication acceptance, independent reproduction, or code inspection is established by the supplied source. [1]
- The arXiv entry is version 1 and was submitted on 5 October 2026.
- It is listed under Computation and Language, with Artificial Intelligence and Machine Learning as additional subjects.
- The record states that code is available, but the supplied evidence does not identify the repository or other destination.
06
What to check before relying on MemPilot
The available record is an arXiv preprint. Readers considering the approach should treat its reported results as author claims until the paper, code, and evaluations can be examined in detail.
- 01
Read the primary record and full paper: https://arxiv.org/abs/2610.06830v1.
- 02
Check the full paper for the five benchmark names, models, baselines, preference settings, hardware, and numerical results.
- 03
Locate and review the code destination before assessing reproducibility, licensing, deployment requirements, or runtime costs.
- 04
Evaluate whether processing raw multimodal history is acceptable for the intended system, since the supplied record does not discuss privacy implications or failure cases.
07
Limits of this edition
The supplied evidence is an arXiv preprint record and abstract, not a peer-reviewed publication or an independent replication. [1]
The record does not identify the five reported benchmarks, evaluated models, baselines, datasets, hardware, preference settings, numerical results, or statistical methods. [1]
The supplied material does not document failure cases, privacy implications of handling raw history, or when runtime curation may add unacceptable cost or latency. [1]
Although the arXiv record states that code is available, the supplied evidence does not provide or inspect the code destination, contents, licence, or reproducibility materials. [1]
SRC
Source desk
Direct links to the material behind this selection. Seeing the source matters as much as reading the synthesis.
Keep exploring
5 Oct 2026
AutoCompact preprint reports learned context management for coding agents
AutoCompact is a newly recorded arXiv preprint proposing learned context-compaction decisions for coding agents. Its authors report benchmark gains over a base model, but the supplied abstract does not establish peer review, independent replication, statistical certainty, or broad generalisation.
30 Sept 2026
Preprint proposes test-time adaptation by revising an AI agent’s workflow
The authors of a new arXiv preprint propose “harness learning”: training a model to revise the executable workflow around a language-model agent from execution feedback. They report gains on reasoning and multi-hop question-answering tasks and transfer to unseen tasks, but the supplied evidence contains no scores, baselines, code, peer review or independent replication.
16 Sept 2026
Preprint proposes a “social harness” for multi-agent AI interactions
The authors of a September 2026 arXiv preprint argue that multi-agent AI systems need a “social harness” for interactions among agents, alongside each agent's personal harness. They report experiments suggesting current tools can fail across trust boundaries and propose layers for prevention, runtime message checks, and later investigation. The available evidence is limited to the preprint record and abstract. [1]